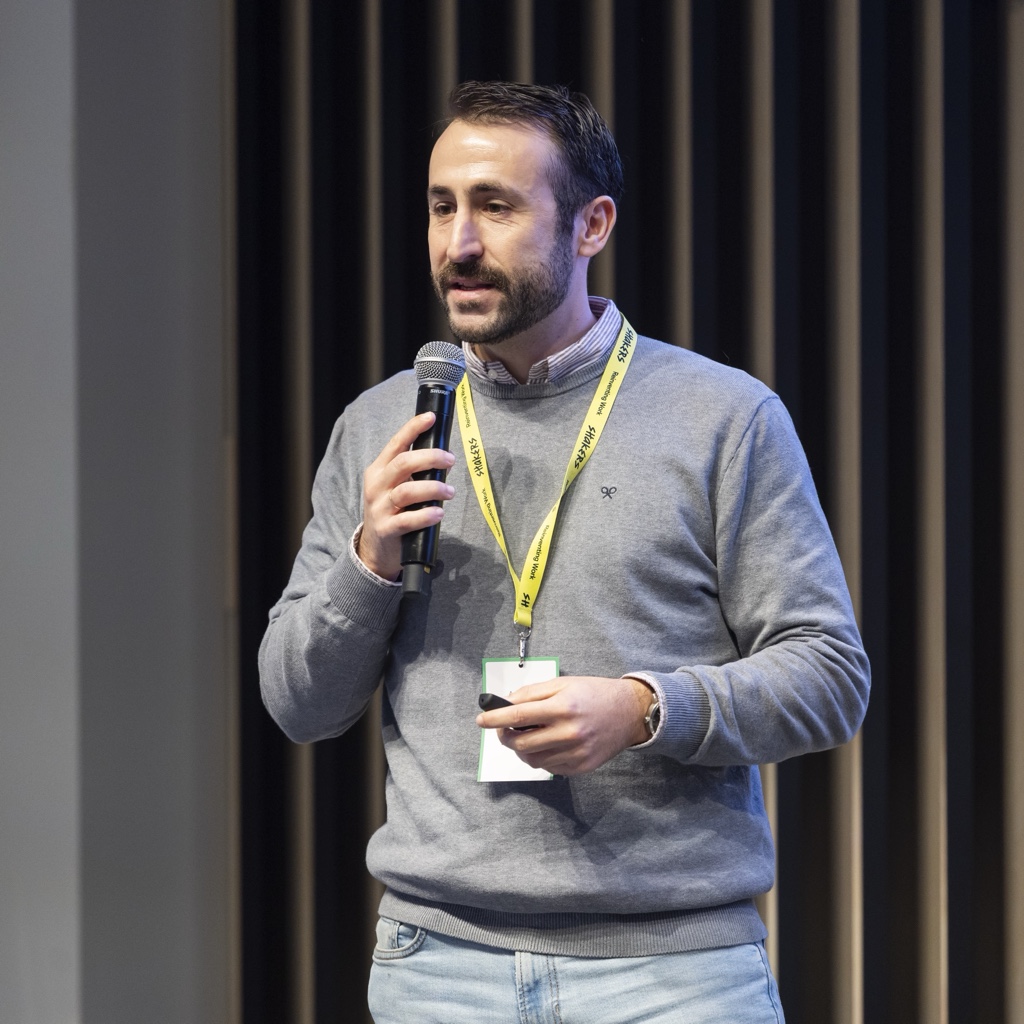
Eduardo
García-Garzón
Head of AI · Shakers · Madrid
About
What most people call an eval is a statistics problem in disguise.
I lead AI at Shakers, where my team ships the matching and agentic systems behind 15,000 freelancers and 600 companies, under EU AI Act constraints. I trained as a psychometrician, and I write here about production AI, evaluation and regulation from the operator seat.
Book a 30-min chat→Latest
More writing
- Benchmark contamination has an older nameOctober 5, 2026
SRE-Bench spent five thousand expert hours keeping its questions secret. Testing has handled that problem for forty years and calls it something else.
- Average adoption returns less than averageSeptember 16, 2026
Ask how the AI programme is going and you get a percentage of people. The denominator is wrong, and the mathematics of the right one is unforgiving.
- Centralize the judgment. Distribute the work.September 5, 2026
McKinsey counted 1,719 leaders in August. Large firms scaling agents jumped to 40%. Firms moving earnings stayed at 6%. Part of that gap is architectural.
Newsletter